LLMs Play Zachtronics' TIS-100
|
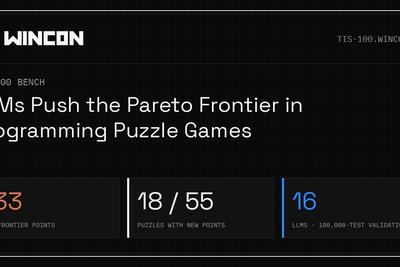
Researchers tested 16 large language models on TIS-100, a challenging programming puzzle game, to see how well they could optimize code solutions. Claude Opus 5.5 and GPT-6 Astra performed best, each solving all 55 puzzles and discovering 11 new frontier points (optimal tradeoffs between cycles, nodes, and instructions), though human players subsequently improved most of the models' solutions within days. The results demonstrate that while LLMs show strong performance on complex optimization tasks, they still fall short of human-level refinement in specialized domains.